ConvShareViT: A Vision Transformer-Like Architecture for Free-Space Optical Accelerators
IEEE Transactions on Neural Networks and Learning Systems, 2026
In brief
Adapts the Vision Transformer so that it can run on a 4f optical system using only convolutions: the linear layers in attention and MLP blocks are replaced by depthwise convolutions with weights shared across channels. Some configurations learn attention comparable to a standard ViT, and the design could in theory run up to 3.04 times faster than GPU inference.
Abstract
Abstract of the arXiv preprint. The published version may differ slightly.
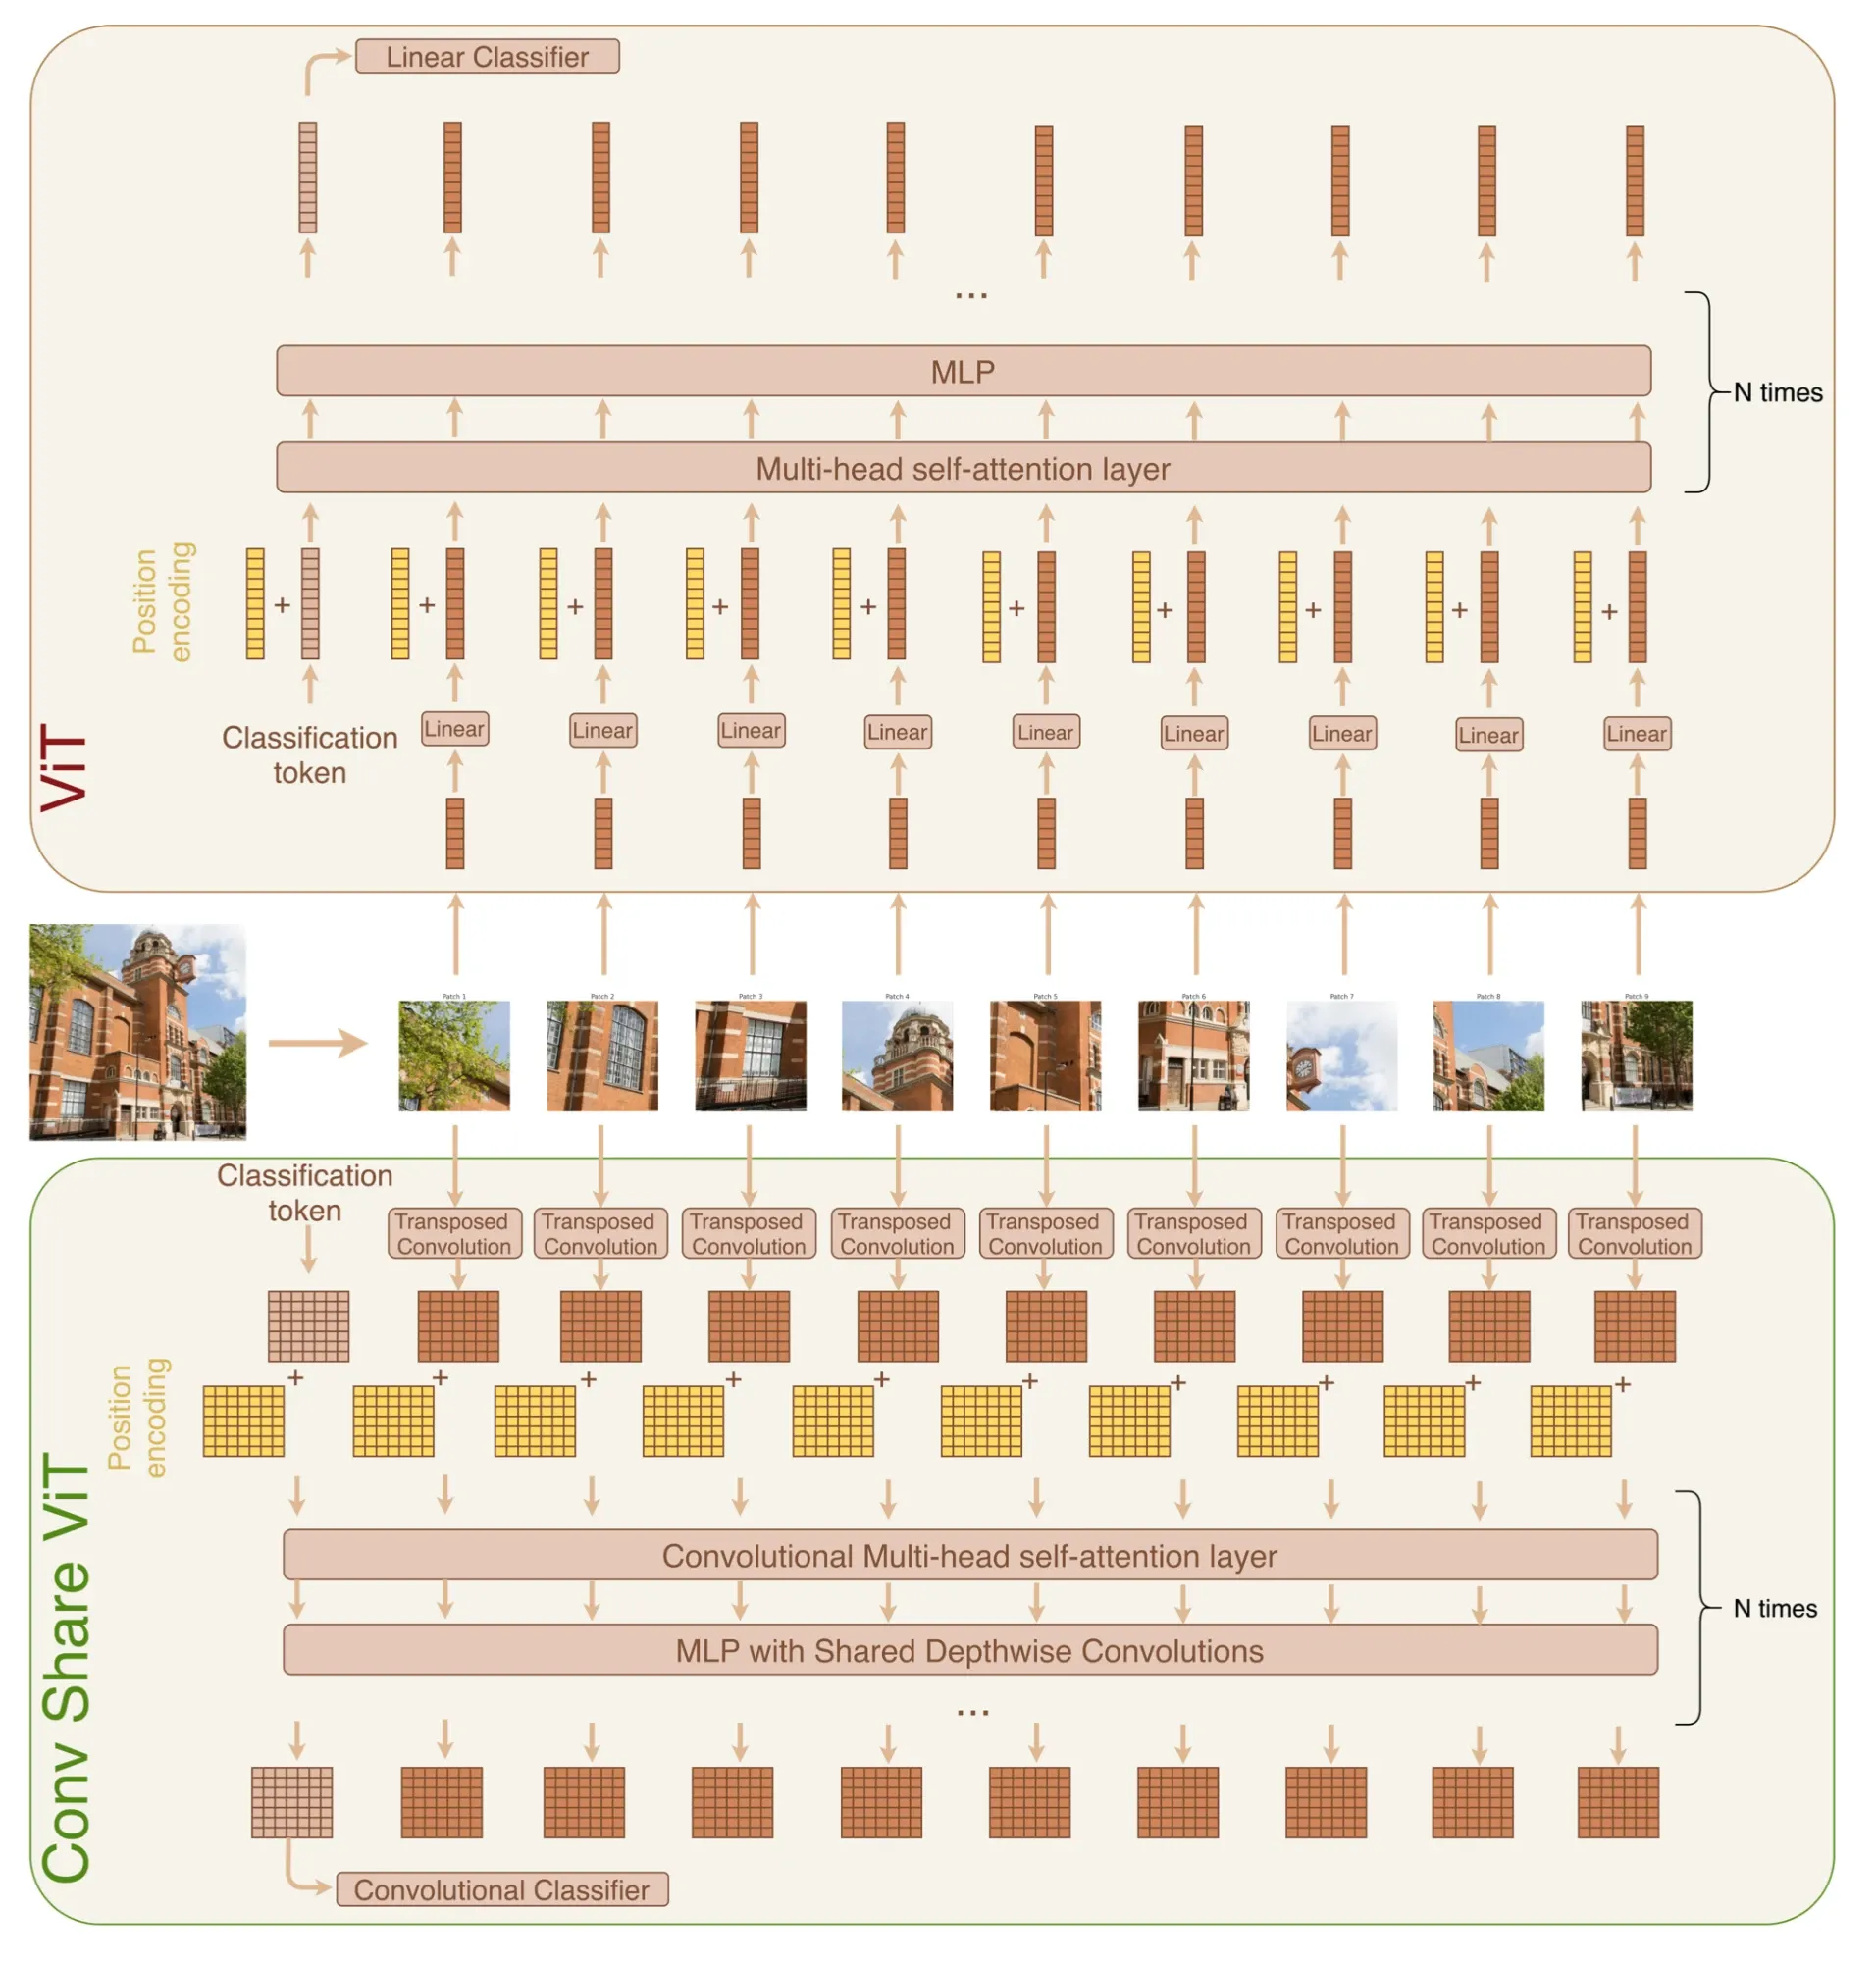
This paper introduces ConvShareViT, a novel deep learning architecture that adapts Vision Transformers (ViTs) to the 4f free-space optical system. ConvShareViT replaces linear layers in multi-head self-attention (MHSA) and Multilayer Perceptrons (MLPs) with a depthwise convolutional layer with shared weights across input channels. Through the development of ConvShareViT, the behaviour of convolutions within MHSA and their effectiveness in learning the attention mechanism were analysed systematically. Experimental results demonstrate that certain configurations, particularly those using valid-padded shared convolutions, can successfully learn attention, achieving comparable attention scores to those obtained with standard ViTs. However, other configurations, such as those using same-padded convolutions, show limitations in attention learning and operate like regular CNNs rather than transformer models. ConvShareViT architectures are specifically optimised for the 4f optical system, which takes advantage of the parallelism and high-resolution capabilities of optical systems. Results demonstrate that ConvShareViT can theoretically achieve up to 3.04 times faster inference than GPU-based systems. This potential acceleration makes ConvShareViT an attractive candidate for future optical deep learning applications and proves that our ViT (ConvShareViT) can be employed using only the convolution operation, via the necessary optimisation of the ViT to balance performance and complexity.
Citation
Riad Ibadulla, Thomas M. Chen, Constantino Carlos Reyes-Aldasoro. “ConvShareViT: A Vision Transformer-Like Architecture for Free-Space Optical Accelerators.” IEEE Transactions on Neural Networks and Learning Systems, 2026. doi:10.1109/TNNLS.2026.3689450